Deployment Strategies: 8 Methods and How to Choose the One for You

Every release is a small bet. Having the right deployment strategies in place determines how much you stand to lose if the bet goes wrong, and how quickly you can recover when it does.
Do you deploy software by pushing everything to the entire user base at once and hoping for the best? Or do you send a new version to a handful of users first, run two production environments side by side, or flip a switch?
The right choice might seem obvious, but it depends on your downtime tolerance, your budget, your CI/CD workflow, and how well you can see what's happening in production.
In this guide, we will walk you through eight common deployment strategies, compare them side by side, and show how feature flags change the risk profile of each one.
You'll also find a practical framework for choosing the right deployment strategy and additional advice for zero-downtime releases and continuous delivery teams.
What are deployment strategies?
A deployment strategy is whichever method you use to move a new version of your software into a production environment. It shapes the whole deployment process, covering how traffic shifts from the previous version to the new version, how much of your user base is exposed at each step, and how you roll back when something breaks.
Let's also decouple deployment from release early on, at least when it comes to defining them:
- Deploying means putting code into an environment.
- Releasing means making that code available to users.
Some strategies treat the two as a single event: the new code goes live and users see it immediately. Others, including the ones that use feature flags, split them apart, so you can deploy on Tuesday and release on Thursday after internal validation.
The strategy you pick shapes your release management process, your infrastructure costs, your blast radius, and the on-call stress your team carries. It sits at the heart of software delivery. A software release that would be trivial with one strategy could become a serious incident with another.
Types of deployment strategies
There's no single best deployment strategy, only trade-offs between risk, speed, cost, and complexity. The types of software deployment strategies below run from the simplest and riskiest to the most sophisticated and safest.
For each one, you'll see how it works, where it fails, and when it fits.
Big bang deployment
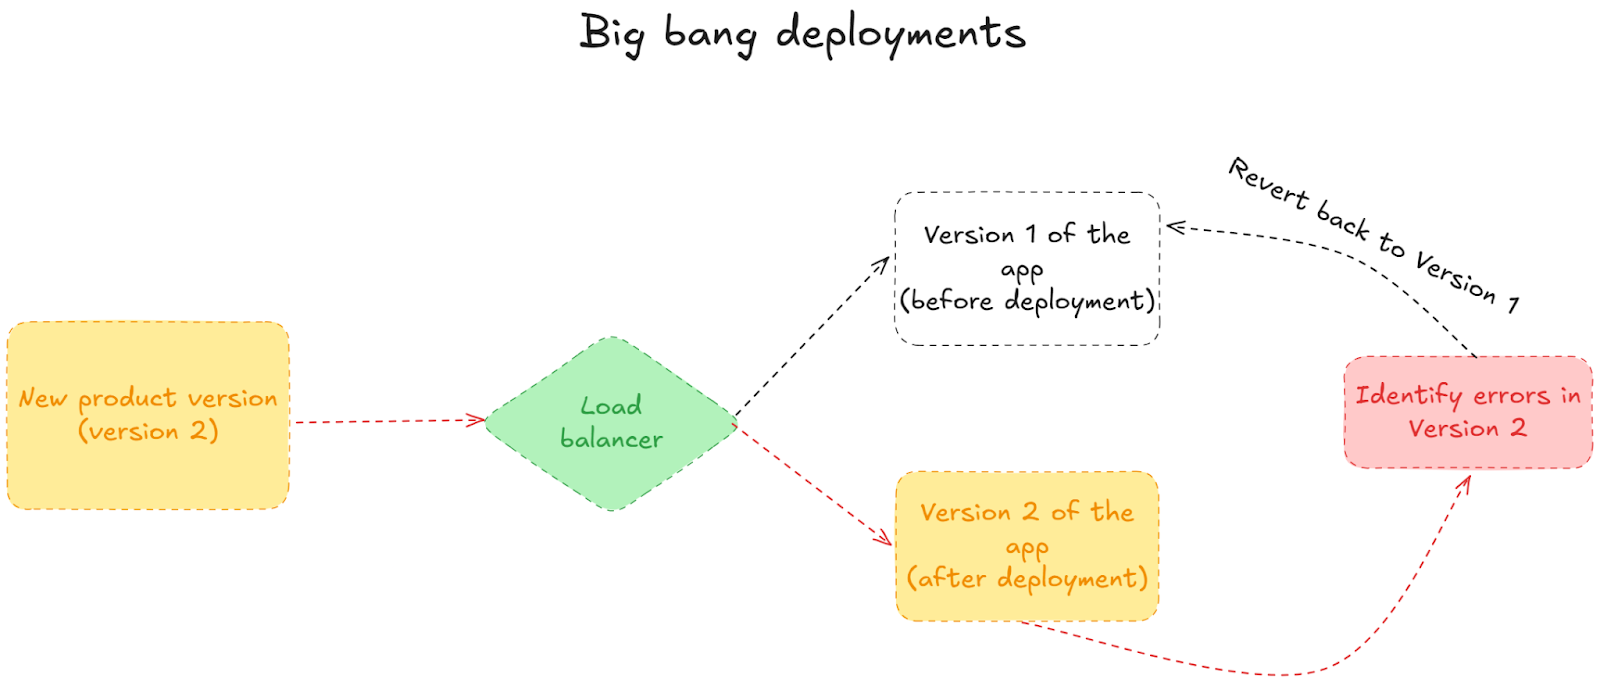
A big bang deployment replaces the whole application in one go. You build, test, and release to the entire user base at once, often overnight or during a maintenance window.
The appeal is that it's simple. There's no traffic splitting, no percentage rollout to manage and no second environment to pay for.
The downside is exposure. If the release has a bug, 100% of your users hit it, and rolling back usually means more downtime on top of the original problem.
Big bang deployment works for small applications, non-critical internal systems, and scheduled maintenance windows where downtime is acceptable. If you're stuck with it, put risky changes behind a kill switch so you can disable them without redeploying.
Recreate deployment
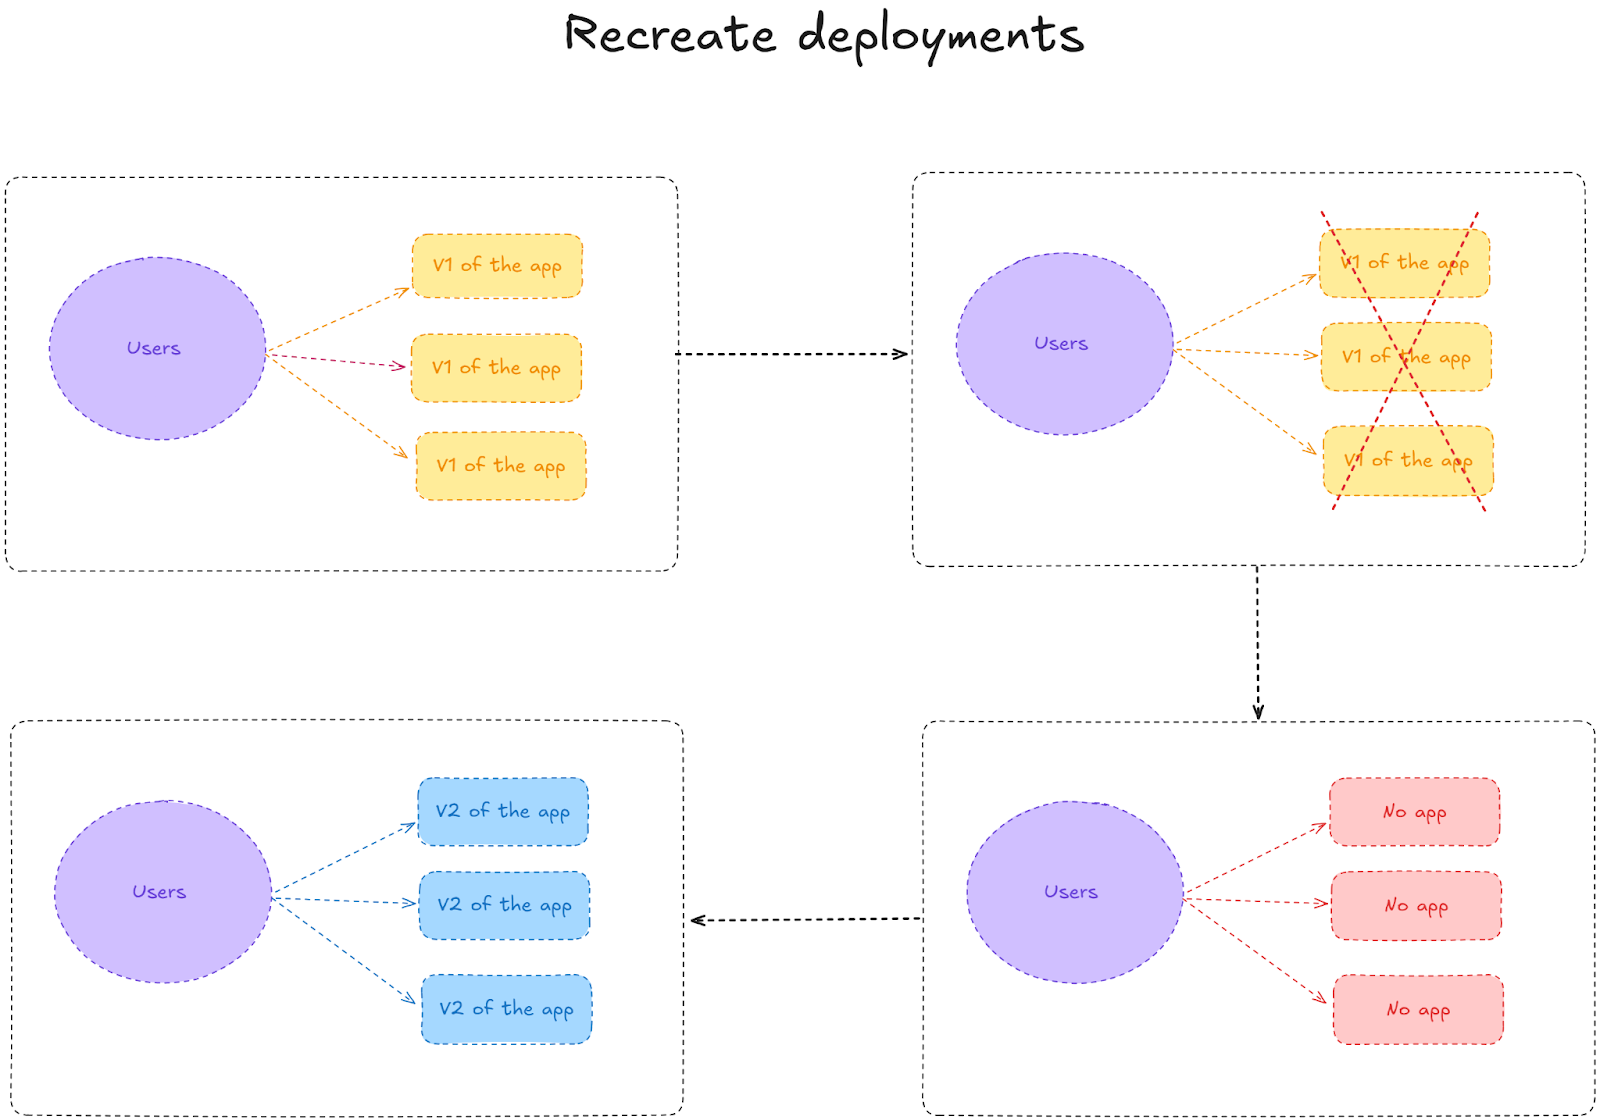
A recreate deployment shuts down the old version completely, then deploys and starts the new version. The application is unavailable while the switch happens.
Recreate and big bang often get used interchangeably, but they describe different things. Big bang is about how much you release at once, while recreate is about how you replace the running infrastructure.
Recreate is cheap and predictable, and it guarantees that old and new versions never run together. Those traits make it useful when a breaking database change means the two versions can't coexist, or for development and staging environments.
The clear negative is that you're guaranteed downtime and a slow, disruptive rollback. For customer-facing services, it's rarely the first choice.
Rolling deployment
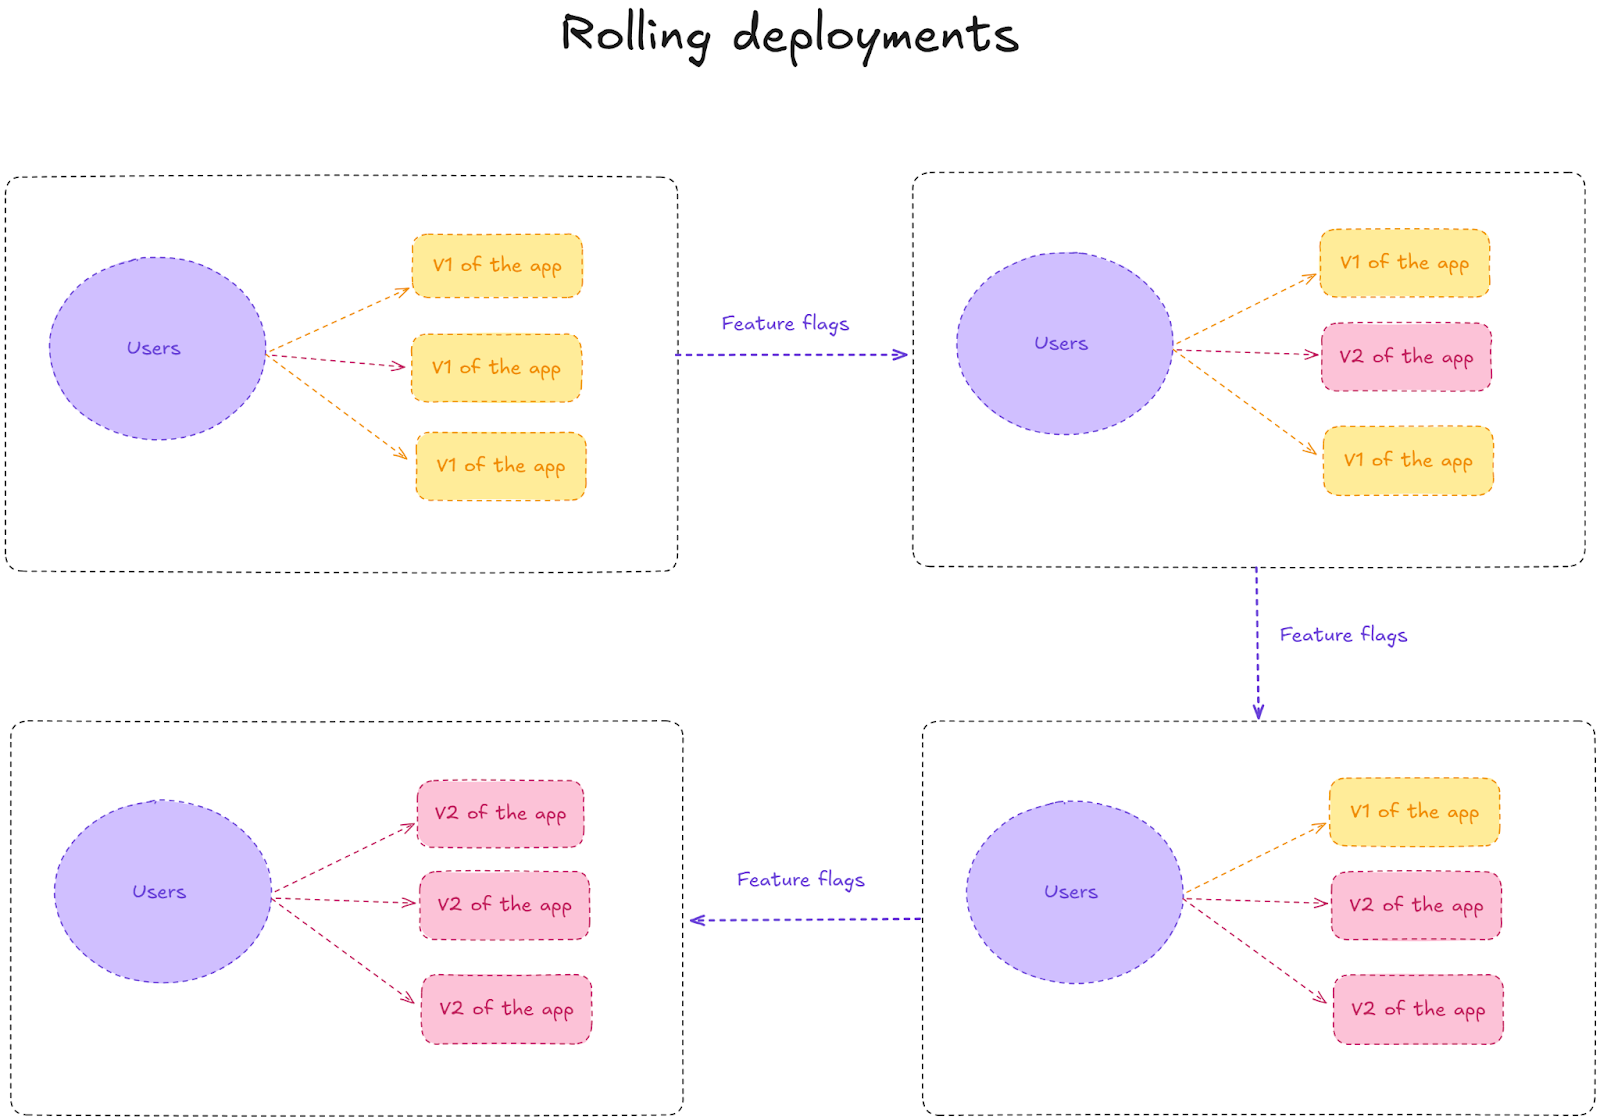
During rolling deployments, you update instances in batches while the application stays live. Kubernetes uses this approach by default: the deployment controller brings up instances of the new version and retires instances of the old version step by step.
Rolling deployments are efficient. You don't need duplicate environments, so infrastructure costs stay close to what you already pay.
The main negatives are caused by the inherent version coexistence. For a while, old and new versions serve production traffic at the same time, so every change has to be backward compatible. Rollback isn't instant either: you have to roll the batches back in the opposite direction.
Rolling deployments suit backward-compatible changes on containerised services where cost is an important factor, and they work as an incremental deployment model when you want incremental releases without new infrastructure.
They are also a sensible starting point if you don't yet have traffic-splitting infrastructure. If you're weighing this against the next option, see our comparison of rolling deployment vs. blue-green.
Blue-green deployment
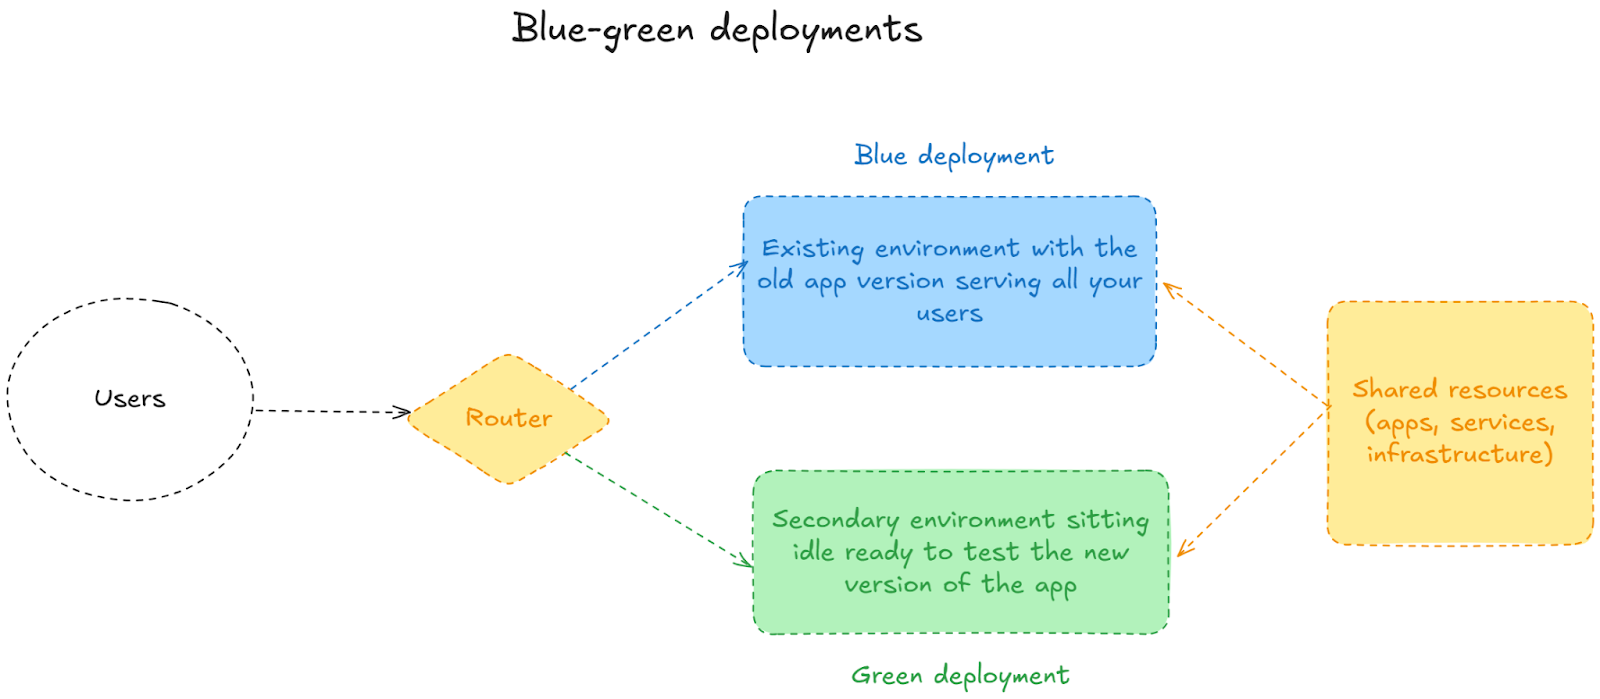
A blue-green deployment runs two identical production environments. The blue environment serves all live traffic while the green environment sits idle. You deploy the new version to green, test it thoroughly, then switch traffic across. If something goes wrong, you switch back.
Its strengths are its near-zero downtime and fast rollback capability. You also get to test the new version in a production-grade environment before any user sees it.
However, on the other hand, by requiring duplicate environments, you roughly double your infrastructure, and both environments usually share one database. Schema changes therefore have to work with both versions of the application at the same time.
Blue-green is a good method if you’re deploying critical applications where fast rollback is a hard requirement, and the budget can stretch to two environments.
Canary deployment
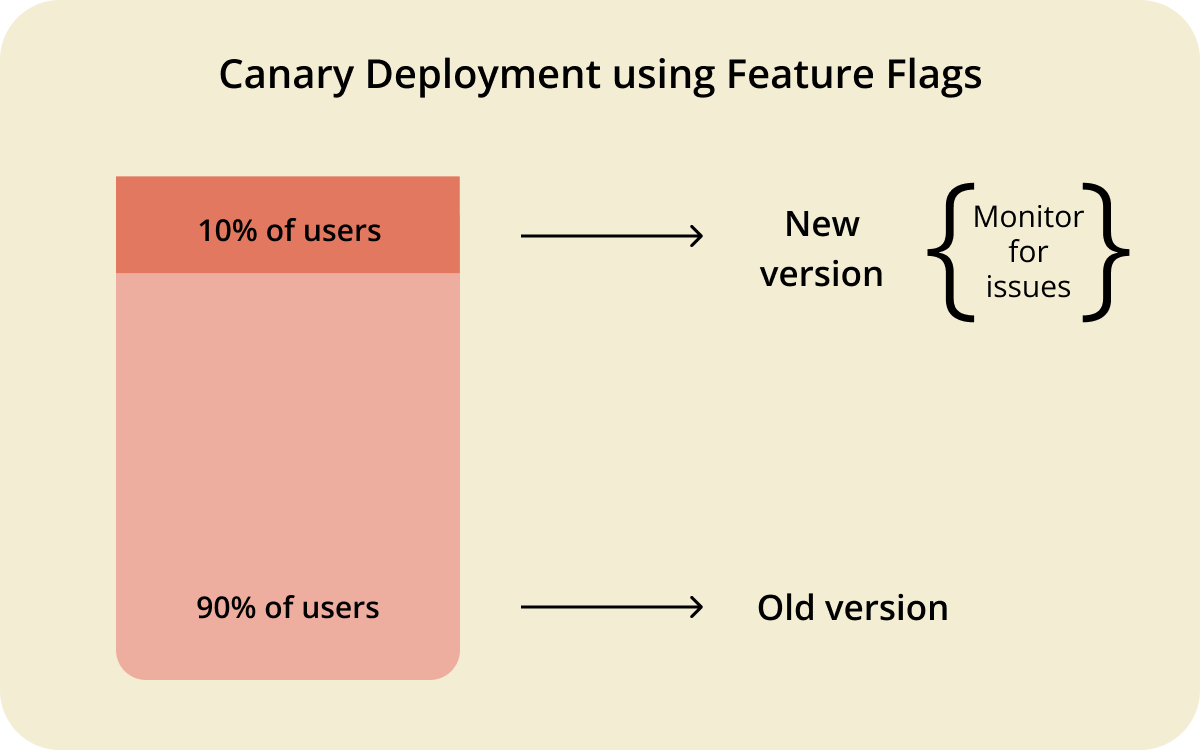
A canary deployment sends a small share of production traffic to the new version while everyone else stays on the current version. The name comes from the canaries coal miners once carried to detect toxic gas.
If the metrics look healthy, you expand the share in steps, which makes it a gradual rollout by design. If they don't, you send all traffic back to the previous stable version. Because real users hit the new code, you get early issue detection, genuine user feedback and customer feedback on new functionality without exposing the entire user base.
Canary requires infrastructure to split traffic, and each new deployment needs a clear observation window. plus monitoring good enough to compare the canary against the baseline. Without that, it's a rolling deployment with extra steps, and system instability can slip through unnoticed. It's also slower than blue-green, since you deliberately wait between stages.
Use canary if you are deploying consumer-facing applications and microservices where a bad release is expensive and you want the observability to spot problems fast.
Shadow deployment
A shadow deployment mirrors real production traffic to a second version of the application. The current version handles every user response. The shadow version processes copies of the same requests, and its responses are discarded or compared offline.
Users are never affected, which makes it the safest way to test how a new version behaves under real load. It's a good fit for algorithm rewrites, machine learning model swaps and migration checks.
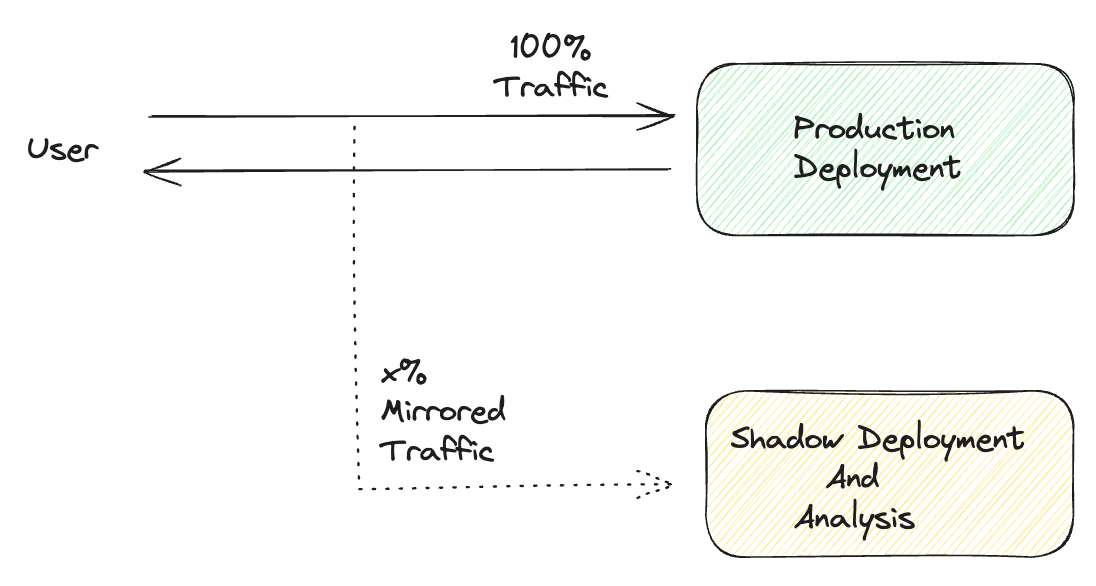
The main risk is in the side effects. If the shadow version writes to a database or triggers payments, those actions happen twice unless you filter them out, which reduces how faithful the test is. You also pay for a full shadow environment and the tooling to mirror traffic.
Shadow deployment tends to be reserved for mission-critical components such as payment processing and authentication. The related idea of a dark launch is when you ship code to production without exposing it to users.
A/B testing
A/B testing is when you route different user segments to different versions so you can compare business metrics such as conversion rate or engagement. Once one version wins with a statistically significant result, you roll it out to everyone.
It looks similar to canary, but the goals differ. Canary determines whether the new version is safe. A/B testing determines which version performs better. It assumes both versions are already stable, making it an experimentation technique rather than a risk-reduction one.
You need a segmentation layer, an analytics pipeline, and enough traffic to reach a reliable result. Without those, the data won't tell you anything.
A/B testing fits user experience changes, pricing experiments and any decision where you want evidence instead of opinions.
Progressive delivery
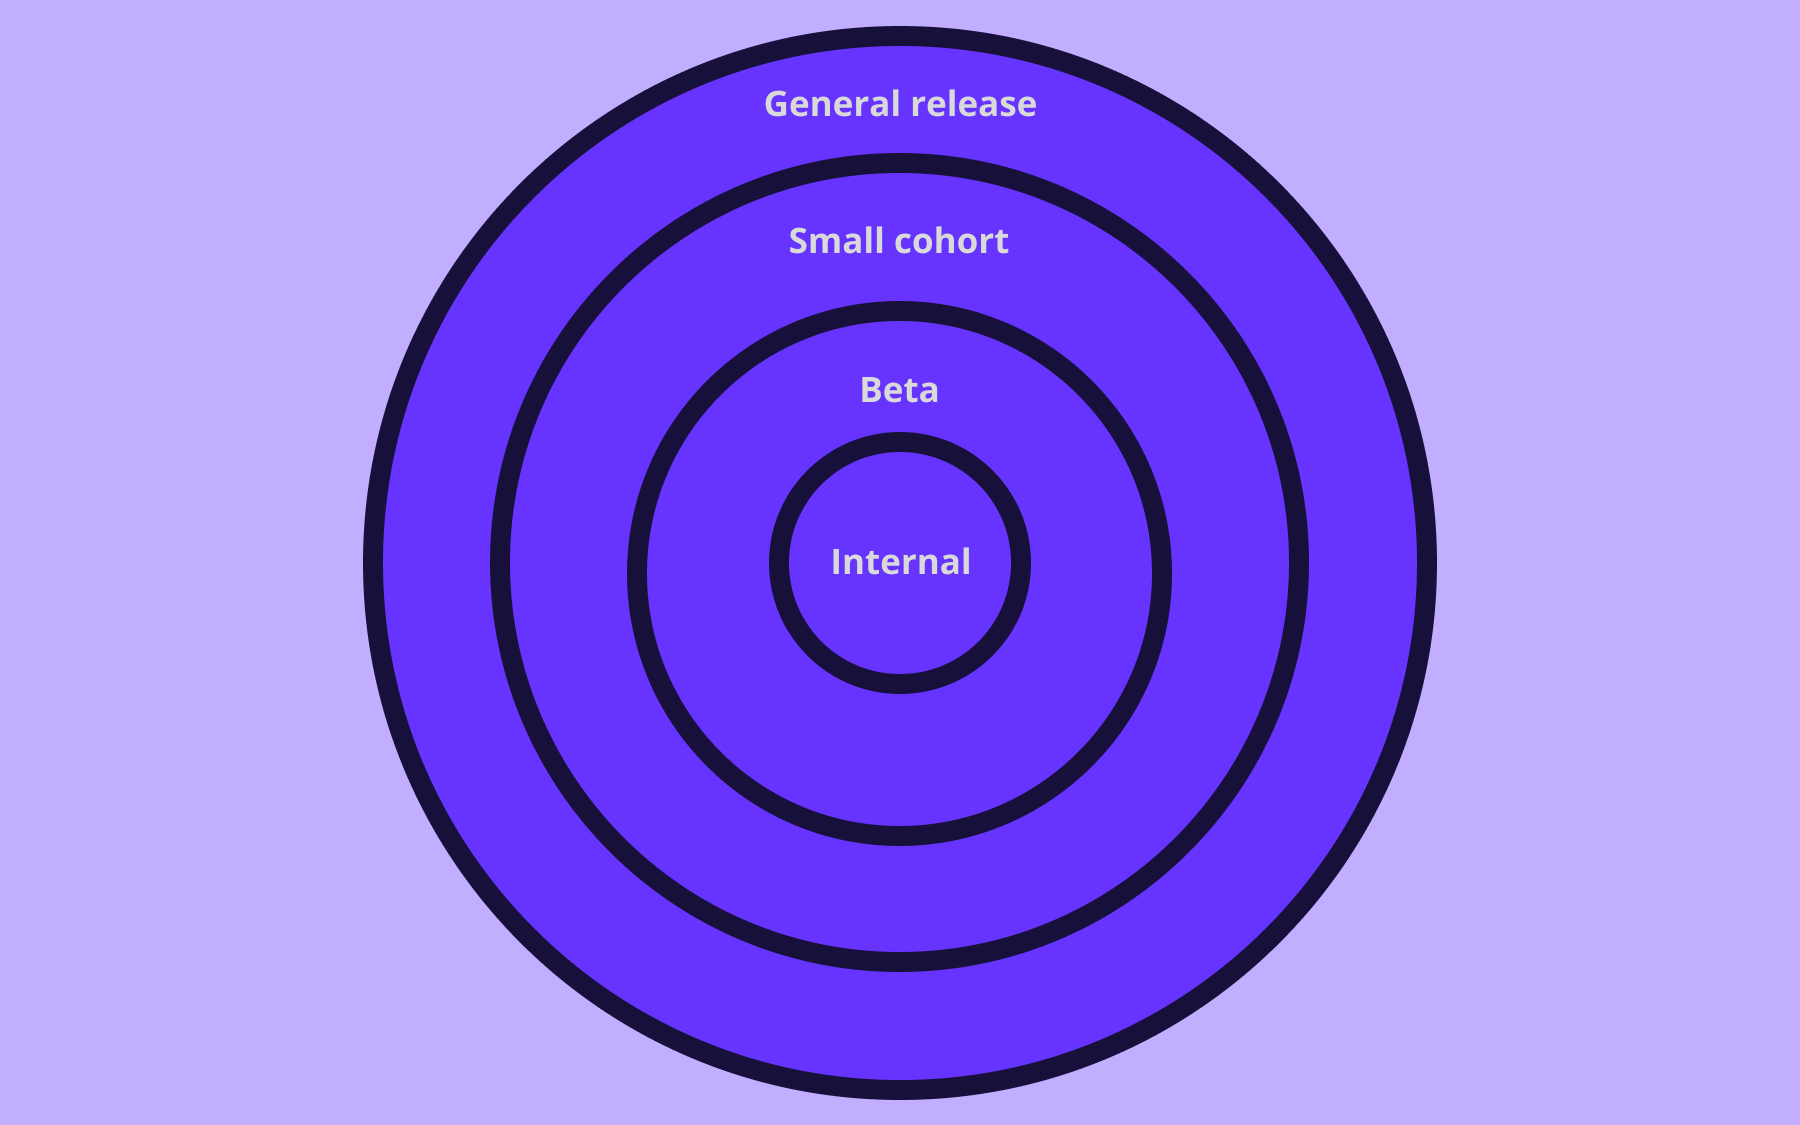
Progressive delivery is a framework rather than a single technique, combining several of the strategies above into one controlled process: deploy to a small audience, watch the results, then widen access based on data.
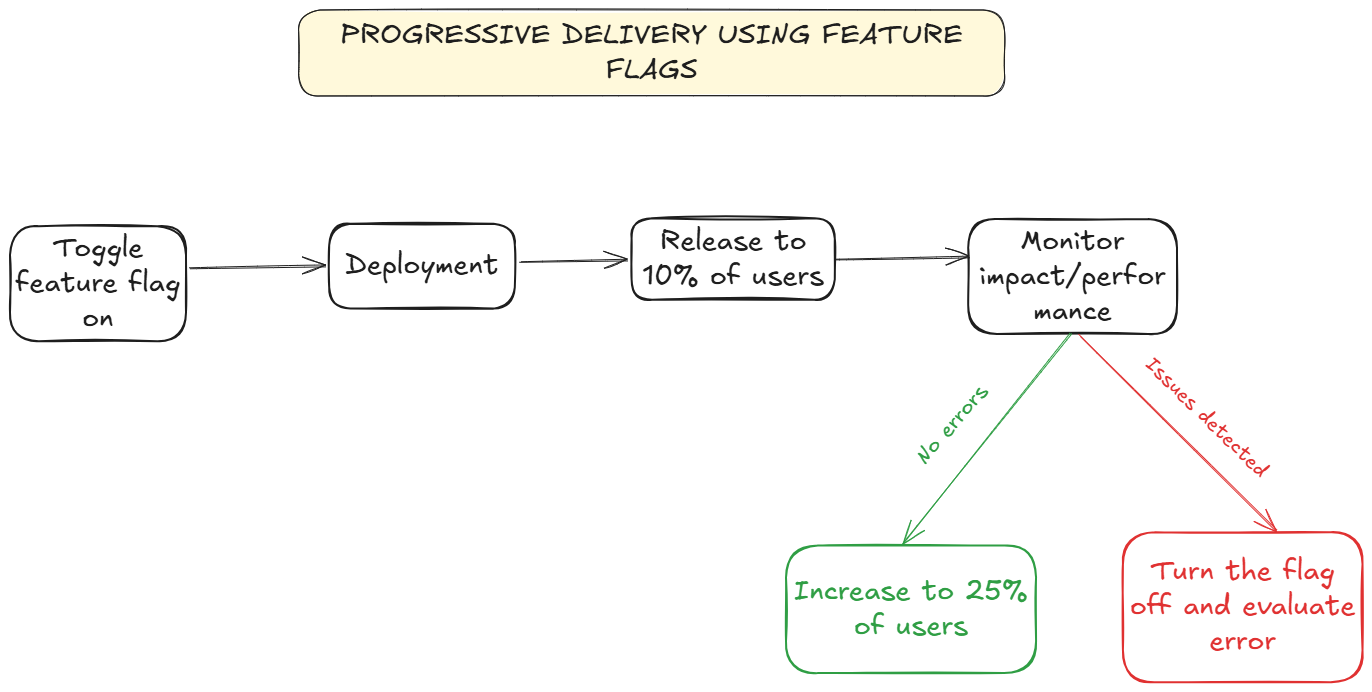
A typical progressive delivery pipeline might start with a canary at 2% of traffic, check error rates and latency against the baseline, then step up to 10%, 25%, 50%, and 100%. Feature flags sit on top, controlling which users see new functionality even after the code has fully rolled out. If any check fails, traffic returns to the previous version automatically.
It offers the lowest release risk of the eight, and the highest complexity. You need mature monitoring, thorough testing and clear guardrails before it pays off. Enterprise applications and complex systems with multiple teams shipping at once are the usual candidates.
Comparing the types of deployment strategy
The table below summarises how the different deployment strategies compare. Ratings are relative, and your own results depend on your architecture and tooling.
The table is a starting point, not a final verdict. A rolling deployment with strong monitoring can be safer than a poorly run canary, and a blue-green setup with a fragile database migration can fail just as badly as a big bang.
How feature flags support deployment strategies
Feature flags enable you to separate deploying code from releasing it. You ship new code that is switched off to production, then turn it on for chosen users when you're ready.
That single change makes several of the strategies above much cheaper and safer, and by integrating feature flags, you have much more control over the more advanced strategies.
Here's how flags fit each approach:
- Big bang. Wrap risky changes in flags so a bad release becomes a switch you flip rather than a full rollback. A kill switch gives you an emergency exit.
- Canary and rolling. Enable a feature for a percentage of users, then increase it in steps for a rolling release with incremental rollouts. Flagsmith supports rollouts by percentage using a percentage split rule inside a segment. For users you identify, the same person stays in the rollout as you raise the number.
- Blue-green. Deploy the new code to your normal production environment behind a flag and reveal it to internal users first. You get much of the blue-green cutover without paying for a second environment.
- A/B testing. Use multivariate flags to split traffic across variations, then send flag data to your analytics platform.
- Progressive delivery. Flags provide the exposure control, while deployment status and deployment metadata from your pipeline tell you when to widen it.
As well as benefits, flags come with their own cons. Every flag adds a code path, a testing matrix, and additional clean-up work. Flags left in the codebase after launch turn into technical debt, so give each one an owner and an expiry date.
Flags also don't replace infrastructure strategies. They can't give you a fresh, tested environment, and they won't help with a change that alters the database structure.
If you work in a regulated industry such as banking, or you build healthcare systems, governance is as vital as speed. Flagsmith records changes in audit logs, and the Scale-Up and Enterprise plans add change requests so a second person can approve changes to production flags. You can also self-host Flagsmith if data residency or on-premises deployment is a requirement.
How to choose the best deployment strategy
To choose the right deployment strategy, start with the constraints you can't change, then move to the ones you can. Work through these factors in order:
- Downtime tolerance. Can the system go offline during a release? If not, rule out recreate and big bang, and consider rolling, blue-green, or canary—with flags.
- Risk tolerance. If a bad release is expensive, favour strategies that limit exposure or restore service quickly, such as canary and blue-green.
- Infrastructure costs. If you can't run a full duplicate environment, blue-green and shadow become less attractive options, while rolling and canary move up as they can reuse existing capacity.
- Rollback capability. Decide how fast you need to recover. Blue-green enables you to switch back almost instantly, while rolling takes as long as the original rollout.
- Team maturity and tooling. Canary and progressive delivery only work if you can split traffic and compare metrics automatically. Start with what your team can support today.
- Architecture. A monolith deploys as one unit, so blue-green or rolling is usually the simplest fit. Microservices benefit from canary or progressive delivery because each separate service can roll out on its own schedule. Serverless functions are often easiest to control with flags.
- Compliance requirements. Regulated teams often need an audit trail and approval steps. Pick a strategy your auditors can follow.
Once you've worked through the list, a few pairings tend to hold up in practice:
Most teams end up combining strategies rather than picking one. For example, a team could use a canary to validate system stability, a flag to control who sees the change, A/B testing to test the change, and a rolling update to handle the infrastructure. The right deployment strategy for your team will also change as your tooling matures.
Best deployment strategies for zero-downtime releases
If your goal is zero-downtime software releases, you are likely between four options: rolling, blue-green, canary, and progressive delivery. Feature flags add a fifth layer, as switching a feature on or off doesn't touch the running application at all.
Zero downtime depends on more than the strategy you pick. To get close to it, you need:
- Health checks so that new instances only receive traffic once they're ready.
- Connection draining, so that in-flight requests finish before an old instance is removed.
- Backward-compatible database changes, where you add new structures first, migrate the data, and only remove the old ones once nothing depends on them.
- Automated testing that runs before any traffic is shifted.
In reality, you are likely aiming for near-zero downtime, and you want to minimise downtime risk rather than promise it away. A blue-green switch is fast, but DNS caches, long-lived connections and shared databases can still cause brief service interruptions. Plan for them instead of assuming they won't happen.
If you can only pick one starting point, rolling deployments plus flags give you minimal downtime at a modest cost. Add blue-green for the services where continuous availability is most important.
Deployment strategies for continuous delivery and agile teams
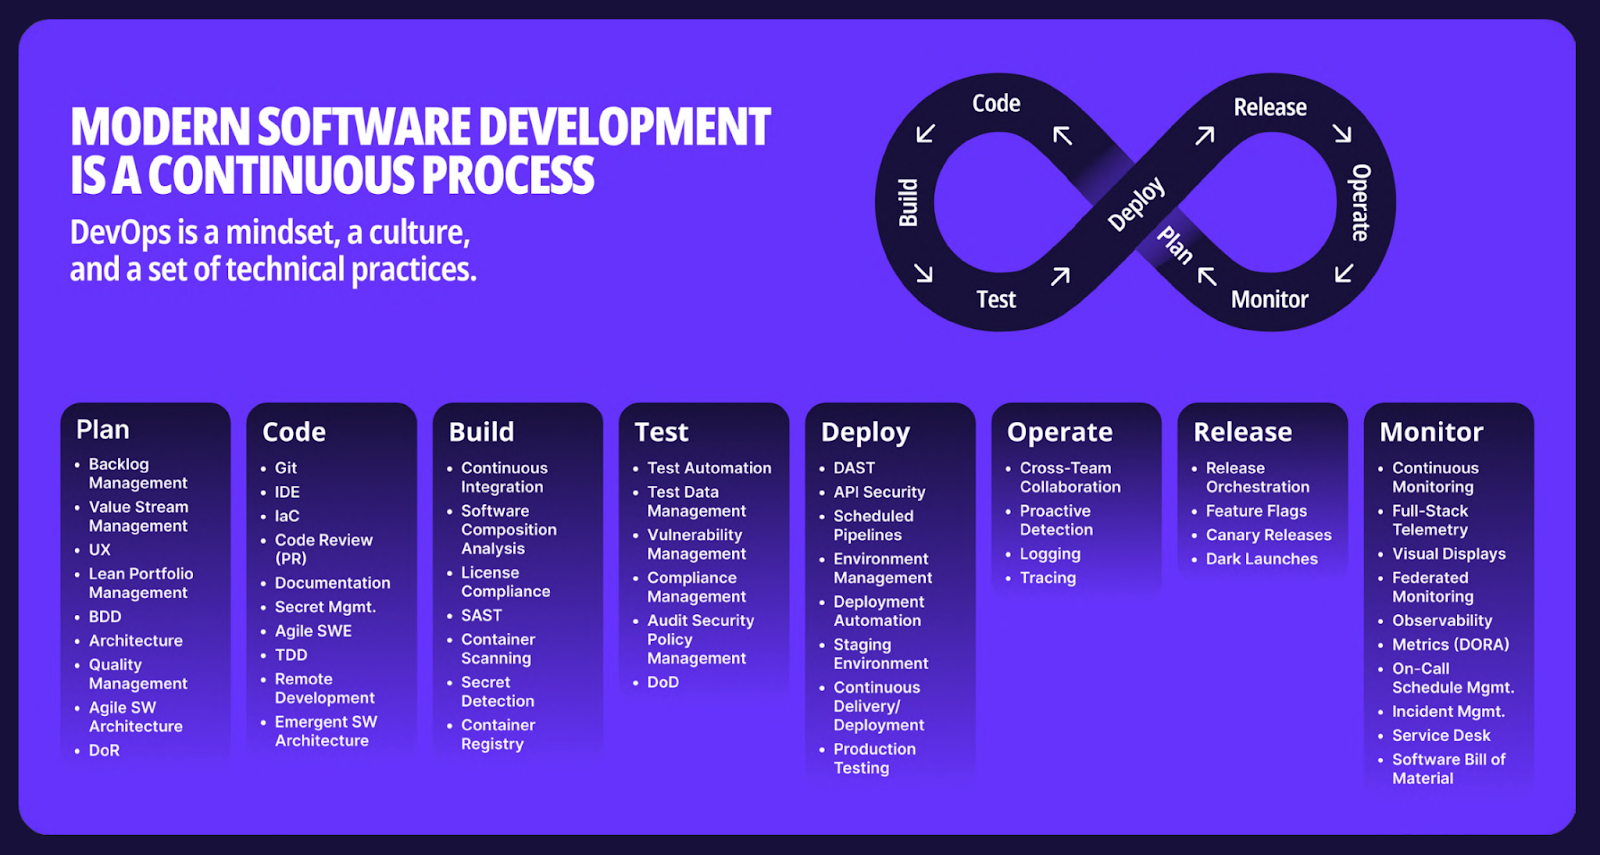
Agile teams often ship small changes during software development, which suits strategies that limit the effect of each one. The aim is to make releases boring while still meeting your business objectives.
- Continuous delivery means every change that passes your pipeline is ready to release, usually with a manual approval before production.
- Continuous deployment removes that step, so passing changes go straight to production.
Our overview of CI/CD pipelines explains how the stages fit together, and deployment frequency is one of the metrics that shows how you're doing.
Your deployment strategy is what happens at the end of that pipeline. A practical path for agile development teams looks like this:
- Start with rolling deployments and feature flags. Merge small changes often, and use trunk-based development so unfinished work stays behind a flag.
- Add automated testing and monitoring, so you can tell within minutes whether a release is healthy.
- Introduce canary releases once you can split traffic and compare error rates and system performance against a baseline.
- Move towards progressive delivery, where automated checks widen or shrink exposure without a person watching a dashboard.
Rollback should be part of the plan from the first step, whatever your cloud provider offers. A clear rollback strategy means a bad release costs minutes instead of hours, and fast recovery makes teams willing to deploy more often.
Conclusion
There's no single best deployment strategy. Big bang and recreate trade safety for simplicity, rolling and blue-green protect availability, and canary, shadow and A/B testing let you learn from production traffic before everyone sees a change.
Pick based on your software project, your downtime tolerance, risk tolerance, infrastructure costs and what your team can monitor. Whichever you choose, separating deployment from release gives you far more control over how new features reach users.
If you want that control, you can sign up for Flagsmith and start rolling features out by user percentage. Flagsmith is open source, supports segments and percentage splits, and runs in the cloud or self-hosted.
Deployment strategies FAQs
What is the difference between deployment and release?
Deployment puts code into an environment. Release makes it available to users. With feature flags, you can deploy code that stays hidden until you switch it on, which lets you release on your own schedule.
Which deployment strategy is best for microservices?
Canary and progressive delivery suit microservices well: each service can roll out independently and be measured on its own. Rolling deployments are a solid default, and flags add per-user control.
What is the difference between canary and blue-green deployment?
Blue-green switches all traffic between two identical environments at once, so it prioritises fast rollback. Canary shifts traffic gradually to a small group first, so it prioritises limiting exposure and gathering feedback.
Which deployment strategies work with Kubernetes?
Kubernetes supports rolling updates and recreate natively. Blue-green and canary are possible with extra tooling such as service meshes, weighted ingress, or a progressive delivery controller.
Can you combine deployment strategies?
Yes, and most teams do. A common pairing is a canary rollout with feature flags for user targeting, running on a rolling update. Progressive delivery is the name for combining them with automated guardrails.









OpenTelemetry, without the vendor lock-in: Introducing full observability for Open Source and Self-Hosted Flagsmith customers